Skip to content
Goodput
Goodput

Same GPU. Different machine.

  • 9 machines
  • 1 provider
  • Rented unannounced
  • Sep–Oct 2026

The listing shows the GPU, which is the same as everyone else’s. Goodput measures the whole machine your customers actually get.

Power, second by second

Power limit setting

About 153 W never drawn

Drew about 247 W

Every setting read 400 W. No cap was shown.

Load starts

Load ends

ResultAbout 14% less compute

One of the capped machines during its re-test, a day after the first measurement. It repeated the result to within 0.1%.

[ Study · Sep–Oct 2026 ]

nine rented machines

One provider, never named. Rented with our own money, without notice.

[ Listed vs delivered ]

The listing only names the GPU.

The customer rents the whole machine. We rented nine machines from one provider, Sep–Oct 2026: the same GPU model at similar prices, and very different machines.

158×

Download speed, similar prices

4,957
Mbit/s, fastest
31
Mbit/s, slowest

8.6×

Disk speed

6,567
MB/s, fastest
762
MB/s, slowest

27.2 / 13.6

CPU cores, identical listing text

27.2
cores, listing A
13.6
cores, listing B

14%

Less compute, on two machines

400 W
power limit setting
about 247 W
actually drawn

Two machines’ settings said 400 W, but they ran at about 247 W. That’s about 14% less compute, and no setting or monitoring showed it.
The same machine re-tested a day later repeated the result to within 0.1%.

2 vs 13

Spread between machines, in percentage points

2 points
managed tier
13 points
marketplace tier

Each machine delivered some share of its GPU’s rated speed. On one provider’s managed tier, those shares stayed within 2 percentage points of each other; on its cheaper marketplace tier, they spread across 13.

In this sample, the managed tier’s real advantage was consistency: something a provider could point to, if it were measured independently.

  • Setting, or the best machine
  • What was actually delivered

[ Across the market ]

Up to 38%

Silicon Data’s study of 3,500+ cloud GPUs found the same GPU model varying by up to 38% across devices and providers.

Silicon Data, “Did You Win the GPU Cloud Lottery?”, GPGPU ’26

8–12%

NVIDIA says its partners’ clusters routinely land 8–12% below its own reference performance, from configuration alone.

NVIDIA, “Exemplar Cloud: lessons for unlocking full performance”

[ The chip ]

The GPU is rarely the whole story.

Across the A100s we measured, the chips matched. What changed from one machine to the next was everything around them: power, connection, disk, network, CPU and RAM.

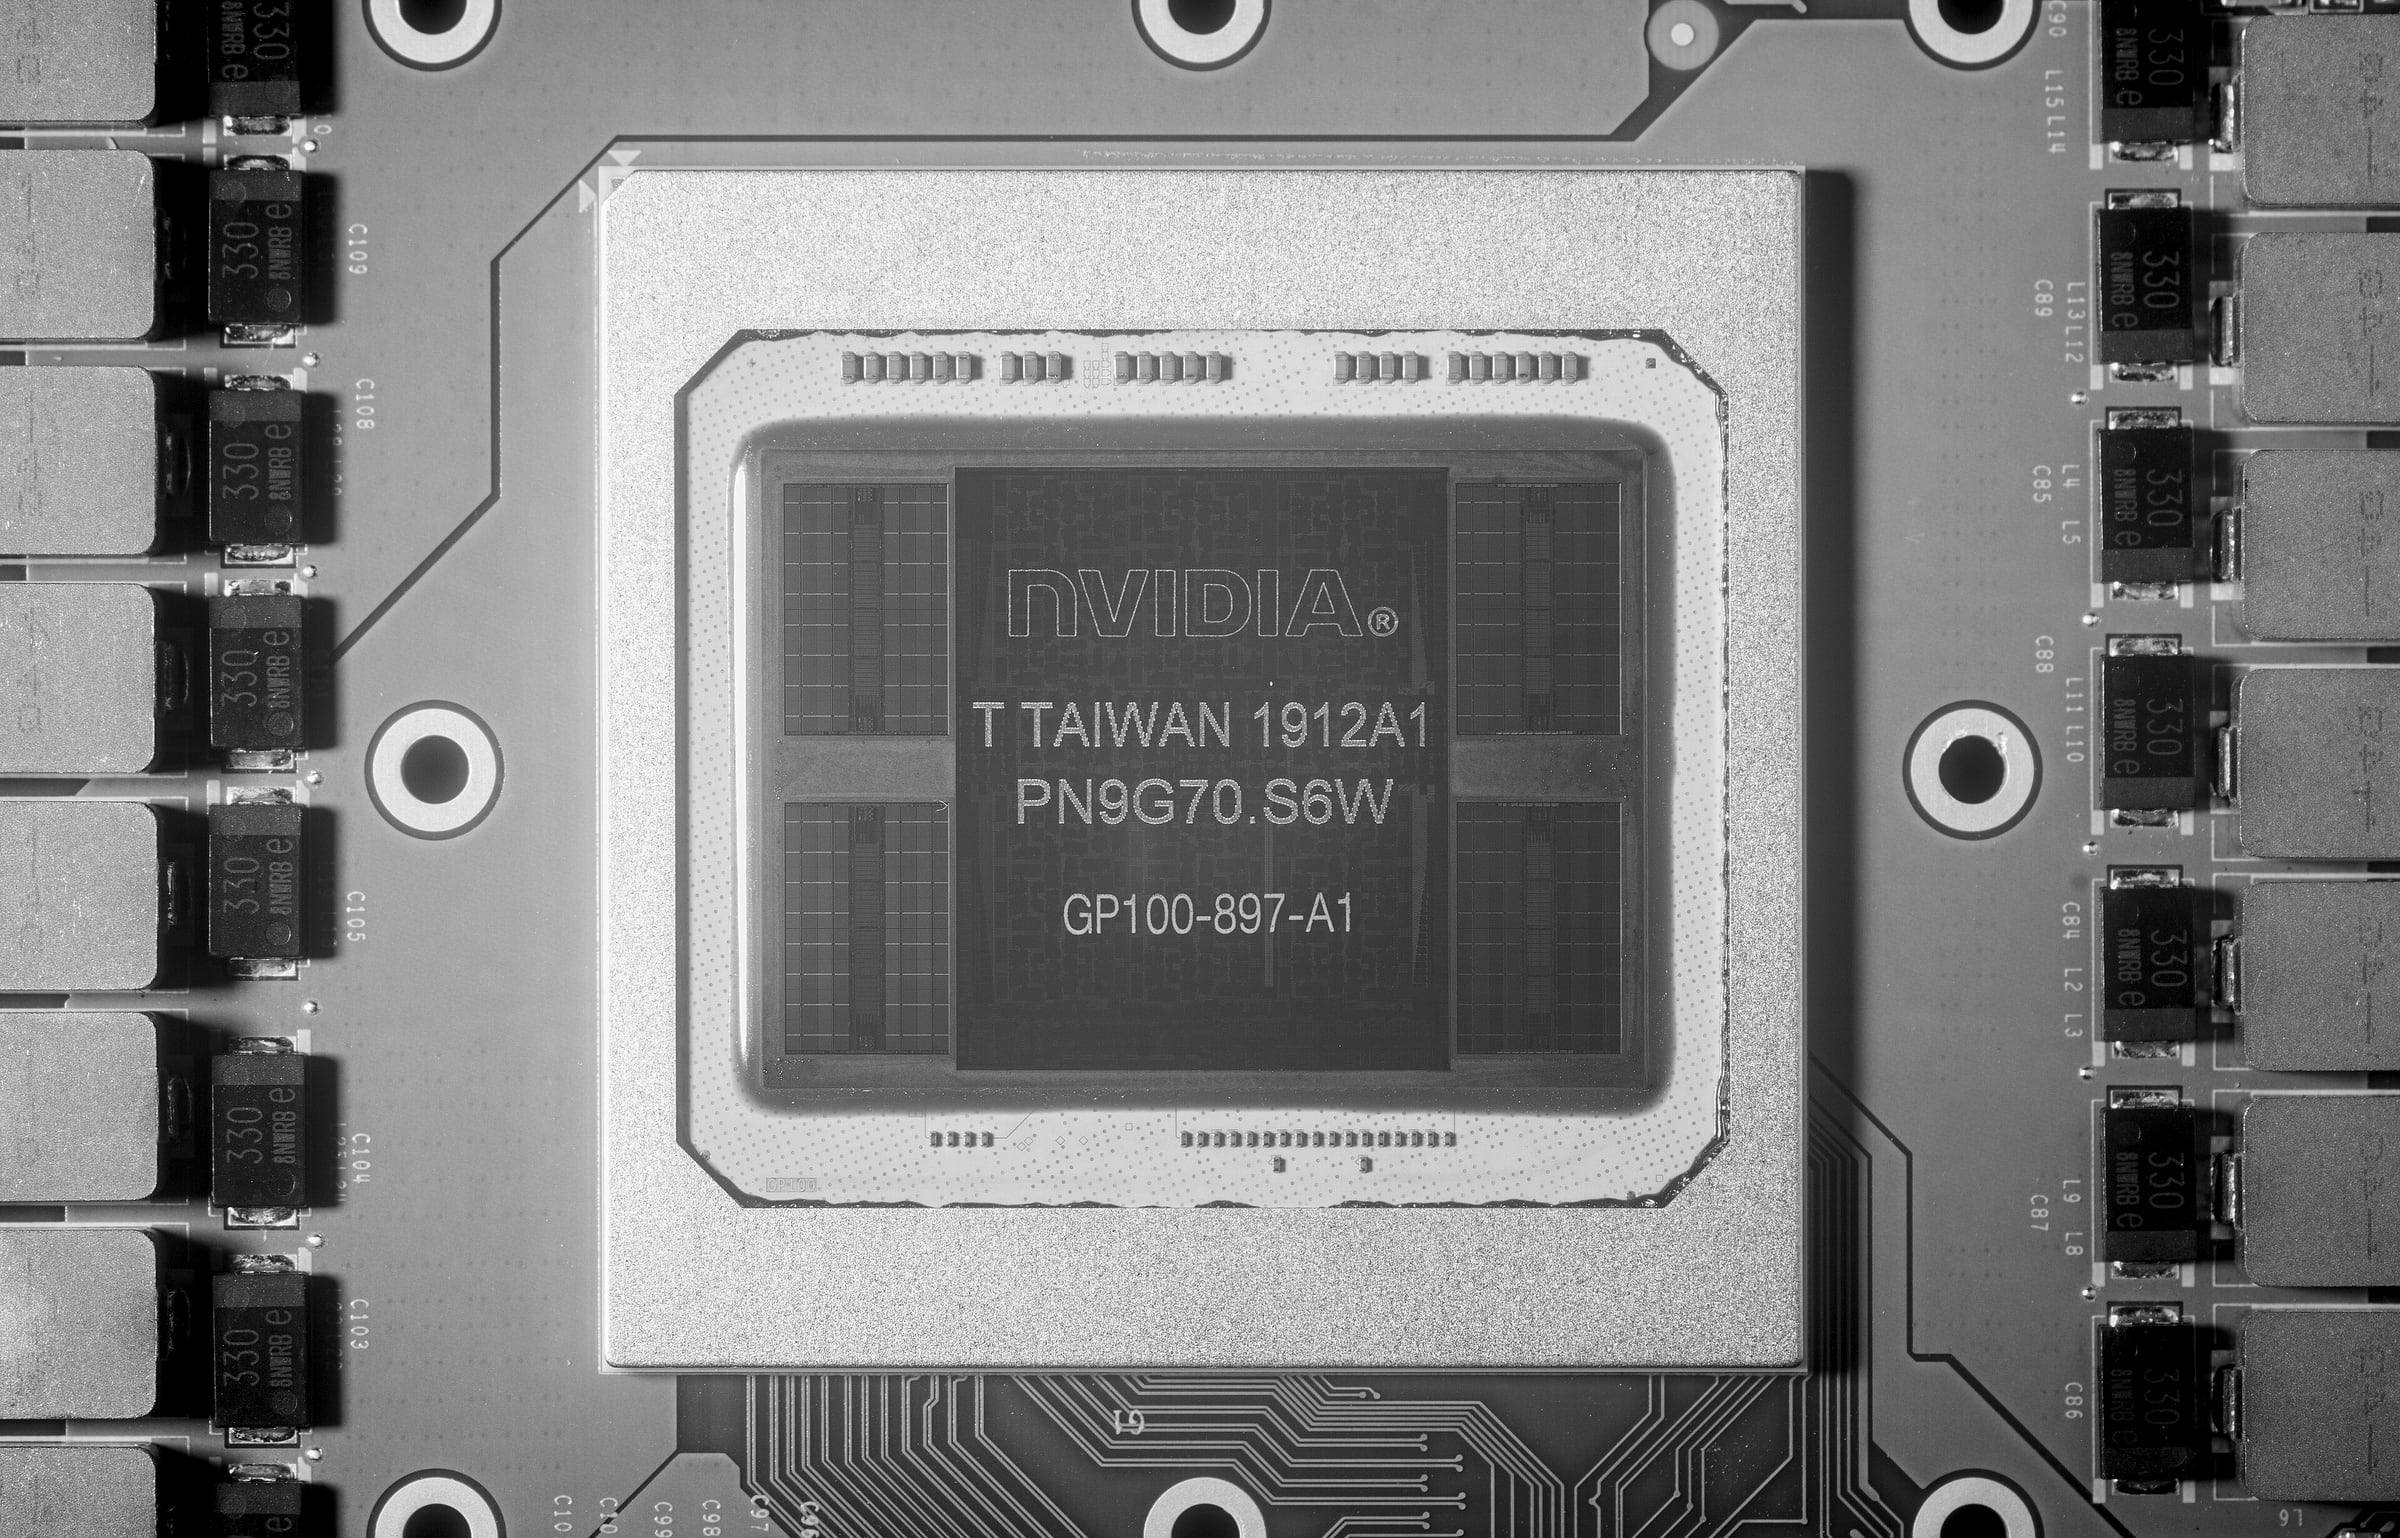
A data-centre GPU chip, close up

Work per clock tick

Within 1%

The GPU chips did the same work per clock tick on every A100 we measured. The chips were fine.

A row of memory modules

Driver versions

5

Nine machines ran five different driver versions. No listing shows which one you get.

[ What varied instead ]

Same GPU model, similar prices.

Power drawn
About 247 of 400 W
Download
158× spread
Disk
8.6× spread
CPU cores
27.2 vs 13.6
A server motherboard with CPU heatsink and memory slots

[ How it works ]

Rented unannounced. Measured in 75 seconds.

Cables bundled at the rear of a server rack

No one is told a test is coming, so no machine can be prepared for it. The fee is the same whatever we find.

Rent like a customer

We rent from the provider’s public listing with our own money, without telling anyone. No machine can be prepared for the test, and the provider can’t tell which rental is ours.

Measure the whole machine

A 75-second measurement of the whole machine the customer actually gets: GPU power and speed, memory, the GPU’s connection to the rest of the machine, disk, network, and the CPU and RAM the container is given.

Report in plain words

A plain-language report: what the machine delivered, what it didn’t, why, and a ranked list of what to fix first. Once finished, it can’t be altered or withdrawn.

[ What we check ]

The whole machine, not just the GPU.

Six groups of checks, run on the machine a customer actually gets. Pick a part to see what we look at.

[ 01 ]

The GPU’s power and speed

Power drawn vs power limit
Can the GPU use all the power it’s rated for?
Clock speed under load
How fast the chip actually runs while working hard.
Slowdown reasons
The GPU’s own explanation for slowing down: power cap, heat, or a setting.
Temperature
Is it overheating?

From our studyTwo machines’ settings said 400 W, but they ran at about 247 W. That’s about 14% less compute, and no setting or monitoring showed it.
A multi-GPU server board with its heatsinks

[ 02 ]

How much work the GPU actually does

Sustained compute
Real work per second under full load, compared with what NVIDIA says the card can do.
Peak vs sustained
Does it slow down after the first few seconds?
Work per clock tick
Is the chip itself healthy?

From our studyThe GPU chips did the same work per clock tick to within 1% on every A100 we measured. The variation came from the machine around the GPU.

A data-centre GPU chip, close up

[ 03 ]

The GPU’s memory

Memory speed
How fast data moves in and out of the GPU’s memory. It matters most for running AI models.
Free memory at start
Is all of it free when you start?
Memory errors
Is the memory starting to fail?

[ 05 ]

The rest of the machine

Network download speed
How fast you can download models and data.
Disk speed
How fast files load and save.
CPU cores you actually get
Processing power your container is really given.
RAM you actually get
Memory your container is really given.

From our studyDownload speed varied 158× (31 to 4,957 Mbit/s) at similar prices. Disk speed varied 8.6× (762 to 6,567 MB/s). Two listings with identical text gave one machine 27.2 CPU cores and the other 13.6.

An NVMe solid-state drive on a PCIe card

[ 06 ]

Basic health and background facts

Correct answers
The GPU’s arithmetic is checked against a known result.
Repeatable answers
The same inputs give the same output.
Whole card or a slice
Did you get the full GPU, or a partitioned share of one?
Driver version, uptime, host CPU
None of these appear in listings.

From our studyNine machines ran five different driver versions.

A server motherboard with CPU heatsink and memory slots

[ Not checked yet ]

Whether another customer shares the machine

This can’t be seen from inside a rented container, and we say so rather than guess.

Clusters of many machines

The networking between servers isn’t tested yet.

Long runs

We measure for 75 seconds, not hours. Slowdowns that build over a long job need a different test.

[ Who it’s for ]

Two sides of the same listing.

[ Audit ]

GPU cloud providers

Independent proof your machines deliver

Your listing shows the same GPU as every competitor’s, so buyers shop on price. Nobody believes a seller’s own numbers, and machines that under-deliver turn into support tickets before you notice them yourself.

What you get

An unannounced audit of your public listings, rented with our own money: which listings under-deliver and why, how consistent each tier is, and a ranked fix list.

What changes

  • A ranked list of which machines to fix first, and where to look
  • Problems caught before customers find them
  • Listings that match what customers actually receive
  • Independent proof for a premium tier

[ Check ]

GPU buyers

Know what you’ll get before you commit

You pick a provider from a spec sheet and a price, then find out mid-run that the network is slow, the disk stalls, or the GPU is held below its power limit by a cap no setting shows.

What you get

A check before you sign a reservation or start a big run. We test the listings anonymously and report compute, power, memory, disk, network and CPU in plain verdicts, so you can compare real compute per dollar.

What changes

  • The real speed of a machine before you commit money
  • Compute per dollar, not just the listed price
  • Fewer runs wasted on slow or faulty machines
  • Measured evidence if you need a different machine

Some providers’ terms forbid benchmarking. If a listing can’t be checked, we’ll tell you before you pay.

A row of memory modules

[ Founding audits ]

Founding audits available for the first providers.

Buyers planning a big commitment are welcome too.

Talk to us

[ A fix list looks like this ]

Examples from real measurements. A real audit lists every listing tested, with the measurement behind each finding.

  • GPU held below its power limit

    High

    about 247 W

    400 W limit

    About 14% less compute, repeated on re-test

    Where to look: Card firmware power policy, server management controller

  • CPU allowance half of a twin machine’s

    Medium

    13.6 cores

    27.2 on its twin

    Slower data loading on the same listing

    Where to look: Container quota settings on that host

  • Slow download speed

    Medium

    31 Mbit/s

    4,957 fastest

    Large models take far longer to arrive

    Where to look: The host’s uplink or network route

  • Slow disk reads

    Medium

    762 MB/s

    6,567 fastest

    Slow loading and slow checkpoints

    Where to look: Storage hardware on that host

[ Sample report ]

What a report looks like.

One real machine, rented and paid for by us, measured with no provider involvement or prior notice.

[ Report · single GPU · A100 80GB PCIe ]

One A100 machine

A managed-tier GPU cloud listing, on demand. Measured without the provider’s knowledge or involvement. The provider is not named.

Verified · no degradation found

[ Read the cause, not just the score ]

A steady number can hide a ceiling.

On the worst machine, the standard stability score ranked it best in the study, because a hard ceiling held flat looks perfectly stable. So a report prints the cause beside the score: power drawn against the limit, clock speed, and the rest of the machine.

Power drawn against the limit

about 247 W of 400 W

One of the two capped machines

About 153 W never drawn

Ask for the full sample report

What was checked

Verdict

PCIe link
Full width
Host power cap
Not capped
GPU memory errors
Clean
Partitioning
Whole card
Under steady load
Stable
Arithmetic
Correct
Run to run
Repeatable

[ Why trust it ]

Built so a good result can’t be bought.

Network switches mounted in a server rack

Nobody believes a seller’s own benchmark numbers. So the terms are fixed before any test runs.

Who rents the machine
Goodput, like any customer
Notice given
None. Rented unannounced
Who pays for the rental
We do, with our own money
The fee
The same whatever the result
A finished report
Can’t be altered or withdrawn
The method
Available on request
Providers named publicly
Never

[ Questions ]

Fair questions, straight answers.

[01]We already have a ClusterMAX rating.

ClusterMAX rates a cluster set up for the test, once a year. We measure what an anonymous customer gets from your public listing, and we can repeat it every quarter.

[02]We run SiliconMark or DCGM ourselves.

You choose the machine and you publish the result, so buyers discount it. Configuration checks also missed our headline case: every setting read 400 W while the GPU ran at about 247 W.

[03]What if you find something bad about us?

You’re never named publicly. Results go to you. A finished report can’t be altered or withdrawn, and that is exactly why the good results are believable.

[04]Nine machines from one provider isn’t much.

Correct. It shows the problem exists; it isn’t a market rate. Silicon Data’s study of 3,500+ cloud GPUs found the same GPU model varying by up to 38% across devices and providers. NVIDIA says its partners’ clusters routinely land 8–12% below its own reference performance, from configuration alone. Each audit grows the sample.

[05]I’ll just benchmark the machine myself.

You can, after you’ve rented it. We test before you commit, across several listings, with the whole machine included, and we know where to look. The cap we found didn’t show in any setting a renter would check.

[06]Are cheap machines always worse?

Not in our data. Each machine delivered some share of its GPU’s rated speed. On one provider’s managed tier, those shares stayed within 2 percentage points of each other; on its cheaper marketplace tier, they spread across 13. Cheap can still be the right choice. The point is knowing which machine you’re getting.

[07]Did a provider cap these GPUs on purpose?

We have no evidence of intent, and our reports never suggest it. We report what the machine delivered and where to look.

[08]What don’t you check yet?

Whether another customer shares the machine (it can’t be seen from inside a rented container), clusters of many machines, and runs lasting hours.

[09]Do you name the providers you test?

Never publicly. Results go to the provider, or privately to the buyer who asked.

[10]What does it cost?

Founding audits are available for the first providers. Get in touch and we’ll scope one with you.

[ Get in touch ]

Talk to us.

Founding audits available for the first providers. Buyers planning a big commitment are welcome too.

Racks of a GPU cluster in a data centre

Start a conversation

There’s no form. Write to this address and you’ll get a reply from Suryansh Sinha.

Write to us

Useful to include

Which listings or GPUs
Links or names
What you’re deciding
Audit, or a check
When you need an answer
A date